OpenAI's Data Agent and the Shift From Answers to Artifacts
💡 Tool Tip:AI Data Analyzer, AI SQL Optimizer, AI Token Counter
On September 10, 2026, OpenAI introduced a Data agent inside ChatGPT Work. The official announcement describes it in one sentence: it connects to your company data, investigates what changed, and builds interactive dashboards you can share. It appears in the Plugins directory in ChatGPT Work under the name Data; administrators can make it available or install it for their teams through Workspace settings, enable and configure the relevant data-source plugins - Databricks and Snowflake are named - and manage who can use them (OpenAI, September 10, 2026). The interesting part is not the model. It is that the deliverable changed shape. You used to get a paragraph. Now you get an artifact your team re-opens next week.
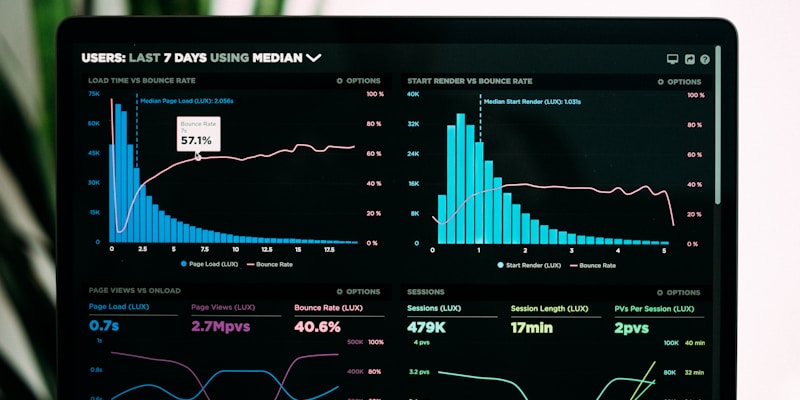
The deliverable moved from an answer to a reusable dashboard
1. The Deliverable Changed, So the Contract Changed
Three verbs carry the announcement: it connects, it investigates, and it builds. The third one is the dividing line, because the output is no longer a paragraph of analysis - it is something that can be opened, edited, and shared again later. That has a direct consequence: anything people re-open becomes a source of truth. A wrong conclusion written into a chat window disappears within hours. A wrong metric written into a dashboard becomes the baseline in next quarter's planning meeting. So the acceptance test for an analytics agent should not be does the answer sound right. It should be will this artifact still hold up in two weeks.
# semantic/metrics.yml - the agent is only as honest as your definitions
metrics:
  net_revenue:
    definition: "gross_revenue - refunds - chargebacks"
    owner: finance-ops
    source: warehouse.fact_orders
    freshness_sla: "4h"
    dimensions: [region, segment, channel]
    tests:
      - not_null(gross_revenue)
      - net_revenue <= gross_revenue
      - abs(net_revenue - (gross_revenue - refunds - chargebacks)) < 0.01

# An analytics agent asked "why did sales slow down" will answer with
# whatever your definitions say. Version the definitions, and the answer
# becomes reproducible instead of improvised.
Connector plugins are the permission boundary
2. What Administrators Are Actually Governing
OpenAI puts access control at the plugin layer. Administrators decide whether the Data agent is available to their teams, enable and configure data-source plugins such as Databricks and Snowflake, and manage who can use them. The implication is clean: what an agent can see is not decided by a prompt, it is decided by which connectors you installed. That turns data governance from an abstraction into a checklist item. Every connector you add is another region of your data that the analytics agent can read, and the connector list is the permission boundary.
-- metric_guard.sql - fail the build when a metric drifts
WITH current AS (
  SELECT date_trunc('day', order_ts) AS day,
         SUM(gross_revenue - refunds - chargebacks) AS net_revenue
  FROM fact_orders
  GROUP BY 1
), baseline AS (
  SELECT day, net_revenue
  FROM metric_snapshots
  WHERE snapshot_date = CURRENT_DATE - INTERVAL '7 days'
)
SELECT c.day,
       c.net_revenue                            AS today,
       b.net_revenue                            AS week_ago,
       ROUND(100 * (c.net_revenue / NULLIF(b.net_revenue, 0) - 1), 2) AS pct_change
FROM current c
LEFT JOIN baseline b USING (day)
WHERE ABS(100 * (c.net_revenue / NULLIF(b.net_revenue, 0) - 1)) > 15;

-- Any row returned is a metric definition change, not a business change.
-- Investigate before you let an agent narrate it to a board.
The semantic layer decides how honest the agent is
3. Where Analytics Agents Actually Fail
Three places. The first is semantic drift: finance, growth, and sales each have a different definition of net revenue, and the agent will faithfully reproduce whichever one you handed it. The second is connector sprawl: a temporary source added to unblock a demo becomes a permanent, unowned channel six months later. The third is untrusted data. An analytics agent is an efficient instruction consumer, so if a spreadsheet, document, or ticket it reads carries hidden instructions, it will follow them - exactly the injection surface OWASP keeps documenting in its agentic security work. None of the three is solved by swapping models.
# dashboards/revenue.yaml - dashboards are code, so they get reviewed
dashboard: net-revenue-overview
owner: finance-ops
version: 12
panels:
  - id: net_revenue_trend
    metric: net_revenue
    grain: day
    window: 90d
    annotations: [pricing_change, outage]
  - id: refund_rate
    metric: net_revenue_refund_rate
    grain: week
    alert: "> 3.5% for 2 weeks"
access:
  viewers: [finance, exec-staff]
  editors: [finance-ops]
refresh: "4h"

# The dashboard the agent builds becomes an artifact under version control,
# not a one-off reply that nobody can re-open next quarter.
4. Treat the Semantic Layer as Product Code
The most effective control against semantic drift is to write metric definitions as versioned files with tests attached: net revenue must equal gross revenue minus refunds minus chargebacks, and it can never exceed gross revenue (code 1). Add a daily guard query that fails the build when a definition change moves a metric more than a threshold week over week (code 2). This looks like data engineering rather than AI work, and that is the point. If definitions are versioned, answers are reproducible. If definitions live in people's heads, answers are luck.
# eval_analytics_agent.py - grade the agent on the questions you care about
CASES = [
    {"q": "Why did net revenue drop in EMEA last week?",
     "must_cite": ["net_revenue", "fact_orders"],
     "must_mention": ["refunds", "channel_mix"],
     "forbidden": ["invented_segment"]},
    {"q": "Which accounts are at renewal risk?",
     "must_cite": ["accounts", "usage_weekly"],
     "must_mention": ["seats_active", "open_tickets"]},
]

def score(answer, case):
    cited = set(answer["sources"])
    return {
        "grounded": set(case["must_cite"]) <= cited,
        "covered": all(k in answer["text"] for k in case["must_mention"]),
        "clean": not any(k in answer["text"] for k in case.get("forbidden", [])),
    }

# Run this on every prompt or model change. Ungraded analytics agents
# quietly become very confident liars.
5. Artifacts, Evals, and Cost: Three Things You Can Ship Now
Put dashboards under version control (code 3), so every change has a review trail, an owner, and an alert threshold instead of living in one person's browser. Then write an evaluation set that states, per question family, which tables must be cited, which dimensions must appear, and what must never appear (code 4) - the characteristic failure of an analytics agent is confidently inventing a segment, and evaluation is the only cure. Finally, account by cost per answered question rather than tokens per month (code 5), because the second number is unactionable by the time you read it.
# budget.py - cost per question, measured per question family
LEDGER = {}

def track(family, tokens_in, tokens_out, cached_in, usd):
    row = LEDGER.setdefault(family, {"calls": 0, "usd": 0.0, "tokens": 0})
    row["calls"] += 1
    row["usd"] += usd
    row["tokens"] += tokens_in + tokens_out
    row["cost_per_question"] = round(row["usd"] / row["calls"], 4)
    return row

# Guardrails that matter for analytics work:
#   - cache the semantic layer and schema, not the question
#   - cap exploratory scans, log every one
#   - report cost per answered question, not tokens per month
6. A Thirty-Day Rollout Order
Week one: enable one connector, one metric family, and three questions; measure accuracy. Week two: move definitions and their tests into the repository so definition changes go through review. Week three: bring dashboard artifacts under source control with alert thresholds attached. Week four: run a look-back. Sample three artifacts from two weeks ago and check whether their conclusions still hold, what they cost, and who approved the connectors behind them. After four weeks you have something better than a demo: an analytics pipeline with an owner.
📌 Frequently Asked Questions
What is OpenAI's Data agent?
Per OpenAI's announcement of September 10, 2026, it is a plugin in ChatGPT Work that connects to approved company data sources, investigates what changed, and builds shareable interactive dashboards. Administrators control availability through Workspace settings.
How is it different from chatting with a database?
The shape of the deliverable. Conversational analysis produces a paragraph; the Data agent produces an artifact a team re-opens, which means it needs version control, an owner, and alert thresholds.
Who decides what data the agent can reach?
Administrators, by enabling and configuring data-source plugins. OpenAI's page names Databricks and Snowflake as examples, and says admins manage who can use them.
What are the most common analytics agent failures?
Semantic drift, where one metric has several definitions, and confident fabrication, where answers are not forced to cite sources. Both are fixed by versioned semantics and evaluation cases.
Which cost metric should govern an analytics agent?
Cost per answered question, not monthly token totals. The first number reflects architectural efficiency; the second is an unattributable lump sum by the time it arrives.
🔧 Recommended Tools
📚 Sources
- OpenAI — Now everyone can put data to work: Data agent in ChatGPT Work (Sept 10, 2026)
- HPCwire / BigDATAwire — OpenAI launches Data agent as enterprise analytics race heats up (Sept 11, 2026)
- Unite.AI — OpenAI introduces Data agent in ChatGPT Work (Sept 10, 2026)
- OWASP GenAI Security Project — State of Agentic AI Security and Governance 2.01